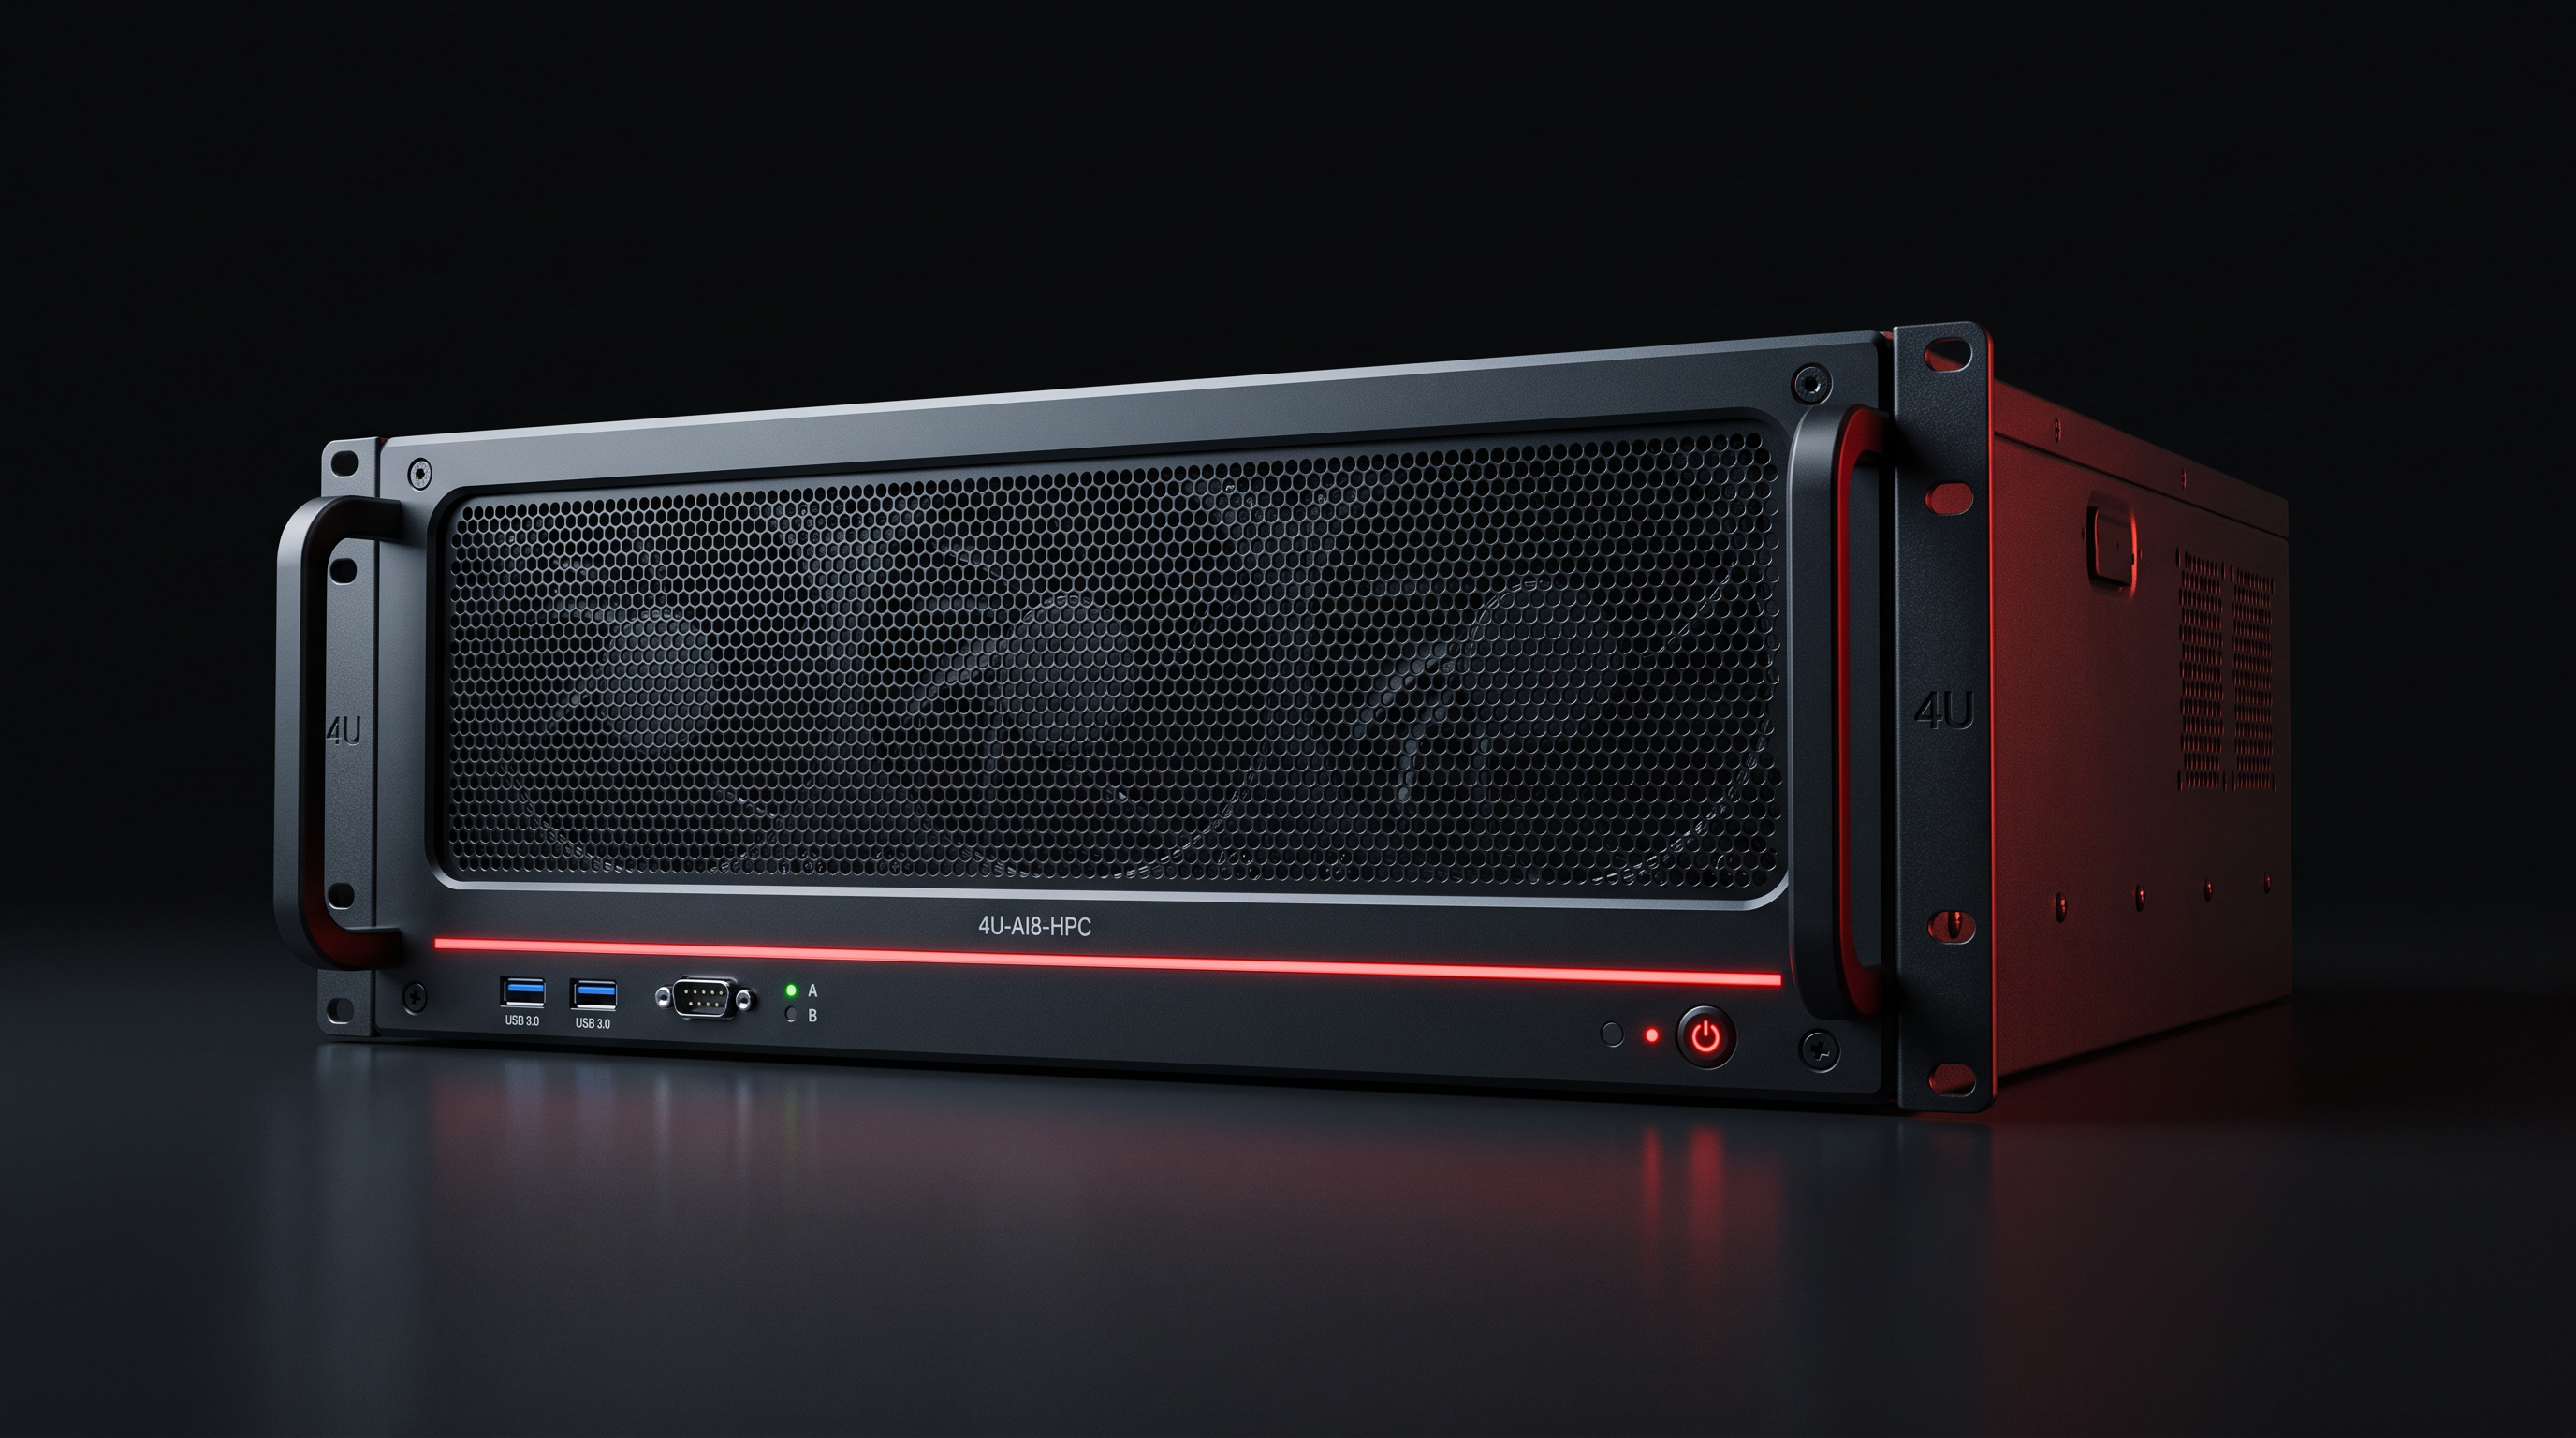
Our flagship reference platform for AI compute in the Middle East. Eight-way SXM5 accelerators, dual EPYC or Xeon SP hosts, and a firmware stack certified for regional sovereign cloud programs. Air-cooled to 40°C, liquid-optional to your rack.
Eight SXM5 accelerators in a fully-connected NVLink Gen4 topology, delivering 900 GB/s of GPU-to-GPU bandwidth without host-side hops.
Runs air-cooled to 40°C ambient in standard GCC deployments. Direct-to-chip liquid loops are a factory option — the same chassis, same firmware, different manifold.
Signed BMC + BIOS with a documented supply chain from server to bezel. Audit-ready under UAE DESC and equivalent GCC sovereign programs.
Optional integration with the T18 Compute Cluster reference rack: pre-cabled InfiniBand fabric, DLC manifold, and top-of-rack management appliance.
Configurable options are marked red. Contact engineering for special-order variants.
| Form Factor | 4U · 448mm depth · DLC-ready |
|---|---|
| Weight | 48.6 kg (fully populated, air-cooled) |
| Sockets | 2× · required |
| CPUs Supported | AMD EPYC 9004 · Intel Xeon SP 5th Gen |
| TDP Envelope | Up to 500W per socket |
| Thermal Design | Air 40°C · Direct Liquid Cooled optional |
| Accelerators | 8× SXM5 · NVLink Gen4 · 900 GB/s |
|---|---|
| NVSwitch | 4× · fully connected topology |
| East-West NICs | 8× 400GbE · 12.8 Tb/s aggregate |
| InfiniBand | NDR 400 · optional |
| GPU-Direct RDMA | Enabled · validated |
| DIMM Slots | 32× DDR5 · 5600 MT/s |
|---|---|
| Max Memory | 2 TB · 4 TB LRDIMM option |
| NVMe | 8× E1.S Gen5 · hot-swap |
| Boot | 2× M.2 NVMe RAID |
| Local Fabric | PCIe Gen5 x16 per accelerator |
| PSU | 6× 3200W Titanium · 4+2 redundant |
|---|---|
| Input | 200–240V AC / 380V DC · single or 3-phase |
| BMC | T18 BMC · Redfish 1.16 · Sovereign FW |
| Security | Silicon Root of Trust · Confidential Compute |
Sovereign cloud training of foundation models with regional data residency guarantees.
Multi-node clusters via NDR InfiniBand or 400GbE RoCEv2 fabrics.
CFD, seismic, and molecular dynamics at hyperscale, with mixed GPU + CPU workloads.
Batch inference and RAG serving with pooled accelerators.
Iterative fine-tuning workflows for enterprise and government tenants.
University and research programs across the Gulf.